Image
Stable Diffusion v1.5
Generate images from text with Stable Diffusion v1.5.
- Text to image
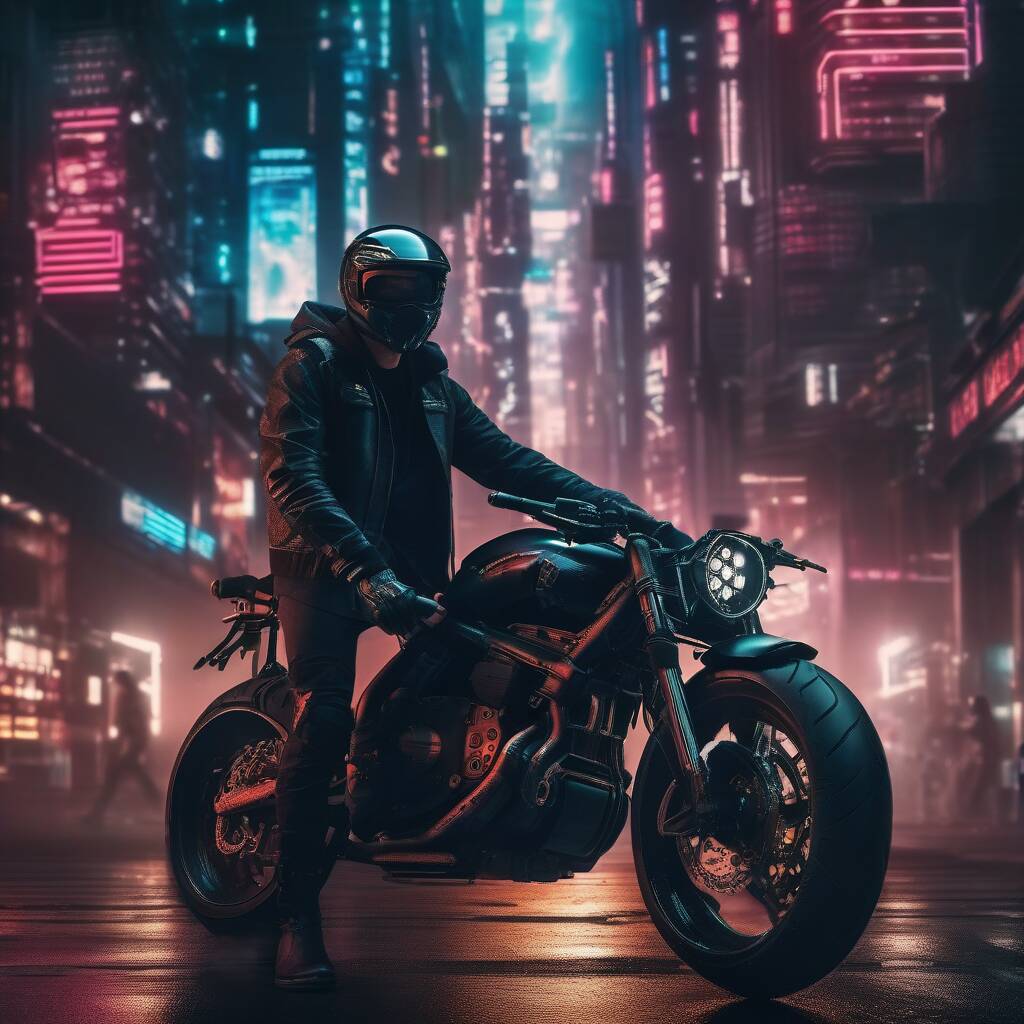
Catalog preview.
Technical details
Review your result
Inspect hands, repeated shapes and any writing at full size.
Inputs and settings
prompt is required; negative_prompt lists unwanted details. loras and embeddings are optional weight inputs, not source photos; omit them unless you have compatible assets.
Use num_images for 1–8 outputs and format for JPEG or PNG. Keep seed fixed while changing guidance_scale or num_inference_steps. expand_prompt can add detail to the brief.
Supported inputs
stable-diffusion-v15
| Input | Type | Requirement | Options and limits |
|---|---|---|---|
prompt | Text | Required | — |
embeddings | List | Optional | — |
enable_safety_checker | On/off | Optional | — |
expand_prompt | On/off | Optional | — |
format | Text | Optional | jpeg, png |
guidance_scale | Number | Optional | ≥ 0 · ≤ 20 |
loras | List | Optional | — |
negative_prompt | Text | Optional | — |
num_images | Whole number | Optional | ≥ 1 · ≤ 8 |
num_inference_steps | Whole number | Optional | ≥ 1 · ≤ 50 |
request_id | Text | Optional | — |
safety_checker_version | Text | Optional | — |
seed | Whole number | Optional | — |